Video2STL: Grounding VLM-Generated Temporal Specifications for Robot Learning
Abstract
Video-based policy learning is particularly promising because it illustrates target behaviors without requiring action annotations or embodiment-matched demonstrations. A central challenge is deciding what information should be transferred from the video to the robot, as existing approaches often make the temporal structure of a task difficult to inspect, ground, and reuse. We present Video2STL, a framework that converts observation-only videos into parametric Signal Temporal Logic (STL) specifications and uses the resulting formal representation for robot learning. A vision-language model first extracts an embodiment-independent semantic event trace and then constructs a bank of symbolic temporal specifications. The model determines the task structure, while numerical predicate thresholds and temporal bounds are grounded from successful robot trajectories. For policy learning, short-horizon specifications provide dense rewards through rolling-window quantitative robustness, while a causal monitor over a retained long-horizon specification provides one-time progress rewards for valid temporal prefixes. Across four manipulation tasks, Video2STL achieves 85.8% average success-once and 67.0% success-at-end, compared with 81.5%/59.5% for native dense PPO and 65.0%/42.3% for Text2Reward. In quadruped locomotion, Qwen-3.8 and GPT-5.6-based Video2STL policies achieve 100% success across velocities from 0.3 to 2.1 m/s while remaining competitive in high-speed energy efficiency.
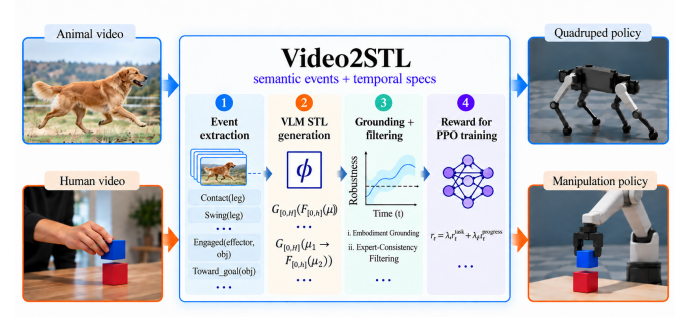
Methodology
Our framework separates symbolic task inference from embodiment-specific grounding. The pipeline consists of four main stages:
- A vision-language model (VLM) maps an observation-only video to an embodiment-independent semantic event trace.
- The trace uses a global ontology to define task-relevant events and pairwise temporal relations without relying on robot-specific metrics.
2. VLM STL Generation
- A second VLM stage translates the semantic trace into a bank of parametric STL formulas.
- At this stage, numerical predicate thresholds and time constants are forbidden; only symbolic parameters are allowed.
3. Target-Embodiment Grounding & Expert-Consistency Filtering
- Successful robot trajectories are split into a grounding set and a held-out filtering set.
- The grounding set is used to fit embodiment-specific numerical parameters and temporal bounds using empirical quantiles.
- The held-out filtering set is used to evaluate each formula, ensuring that only specifications compatible with successful target-embodiment behaviors are retained.
4. Two-Timescale Temporal Reward
- Short-horizon specifications: Evaluated on a trailing window to provide dense, local policy feedback via smooth robustness.
- Long-horizon specifications: Monitored causally, yielding a one-time sparse progress reward when a new valid stage of the temporal sequence is reached without violating required order or deadlines.
Experimental Results
Quadruped Locomotion
Evaluated on Google’s Barkour vb quadruped in MuJoCo XLA (MJX) across a range of commanded forward velocities. Policies are evaluated using 20 independent rollouts of 500 simulation steps. Survival and velocity-tracking success are reported as percentages (higher is better), and CoT denotes cost of transportation (lower is better).
| vx (m/s) |
Video2STL (GPT-5.6) |
Video2STL (Qwen 3.8) |
Text2Reward |
Heuristic |
| Surv. ↑ | Succ. ↑ | CoT ↓ |
Surv. ↑ | Succ. ↑ | CoT ↓ |
Surv. ↑ | Succ. ↑ | CoT ↓ |
Surv. ↑ | Succ. ↑ | CoT ↓ |
| 0.3 | 100% | 100% | 2.63 | 100% | 100% | 2.63 | 100% | 100% | 0.91 | 100% | 100% | 1.20 |
| 0.5 | 100% | 100% | 1.80 | 100% | 100% | 1.86 | 100% | 100% | 0.80 | 100% | 100% | 1.00 |
| 1.0 | 100% | 100% | 1.26 | 100% | 100% | 1.37 | 100% | 100% | 0.74 | 100% | 100% | 1.00 |
| 1.6 | 100% | 100% | 1.12 | 100% | 100% | 0.92 | 100% | 100% | 0.87 | 100% | 100% | 1.30 |
| 1.9 | 100% | 100% | 1.13 | 100% | 100% | 0.98 | 100% | 100% | 1.00 | 100% | 100% | 1.40 |
| 2.0 | 100% | 100% | 1.13 | 100% | 100% | 1.00 | 100% | 100% | 1.07 | 100% | 5% | 1.40 |
| 2.1 | 100% | 100% | 1.15 | 100% | 100% | 1.02 | 100% | 100% | 1.14 | 100% | 0% | 1.40 |
Robot Manipulation
Evaluated in ManiSkill3 using native task success conditions across 128 episodes. We report “Success Once” (the condition is reached at least once) and “Success at End” (the condition is met in the final state).
| Task |
Video2STL |
Text2Reward |
Native Dense PPO |
| Succ. Once ↑ | Succ. End ↑ |
Succ. Once ↑ | Succ. End ↑ |
Succ. Once ↑ | Succ. End ↑ |
| PushCube | 0.95 | 0.93 | 0.65 | 0.23 | 1.00 | 0.84 |
| StackCube | 0.98 | 0.95 | 0.98 | 0.96 | 0.73 | 0.52 |
| LiftPegUpright | 0.59 | 0.05 | 0.97 | 0.50 | 0.98 | 0.47 |
| PlaceSphere | 0.91 | 0.75 | 0.00 | 0.00 | 0.55 | 0.55 |
Quadruped Locomotion Videos
Below are qualitative evaluations for different reward formulations across low (0.4 m/s), medium (1.2 m/s), and high (2.0 m/s) velocity commands.
Video2STL (GPT-5.6)
| vx = 0.4 m/s |
vx = 1.2 m/s |
vx = 2.0 m/s |
|
|
|
Video2STL (Qwen 3.8)
| vx = 0.4 m/s |
vx = 1.2 m/s |
vx = 2.0 m/s |
|
|
|
Video2STL (Gemini)
| vx = 0.4 m/s |
vx = 1.2 m/s |
vx = 2.0 m/s |
|
|
|
Text2Reward
| vx = 0.4 m/s |
vx = 1.2 m/s |
vx = 2.0 m/s |
|
|
|
Heuristic Baseline
| vx = 0.4 m/s |
vx = 1.2 m/s |
vx = 2.0 m/s |
|
|
|
Robot Manipulation Videos
PushCube
| Video2STL |
Text2Reward |
Native Dense PPO |
|
|
|
StackCube
| Video2STL |
Text2Reward |
Native Dense PPO |
|
|
|
LiftPegUpright
| Video2STL |
Text2Reward |
Native Dense PPO |
|
|
|
PlaceSphere
| Video2STL |
Text2Reward |
Native Dense PPO |
|
|
|
Citation